Relative Frequency Calculator
Instantly analyze probability subsets. Determine precisely what proportional fraction or decimal percentage a distinct subgroup represents within an absolute total dataset.
📋 Table of Contents
- Interactive Relative Frequency Calculator
- What is Relative Frequency? (Core Definition)
- The Universal Statistical Formulas
- Absolute vs. Relative vs. Cumulative Frequency
- How to Calculate It Step-by-Step (With Examples)
- Creating a Relative Frequency Distribution Table
- Why is it Critical in Probability Theory?
- Common Mathematical Mistakes to Avoid
- Frequently Asked Questions (FAQ)
🧮 Interactive Relative Frequency Calculator
Input the raw occurrences of your distinct event (the subgroup) and the absolute amount of total trials observed. Our built-in statistical engine will instantaneously extrapolate the relative frequency across all three standard probability formats.
Enter whole-number counts using 1–30 digits only, without signs, decimals, commas or exponents. The total must be positive and the event count cannot exceed it. Fractions are exact; ≈ marks rounded results (4 decimal places or 2 percentage decimal places).
📘 What is Relative Frequency? (Core Definition)
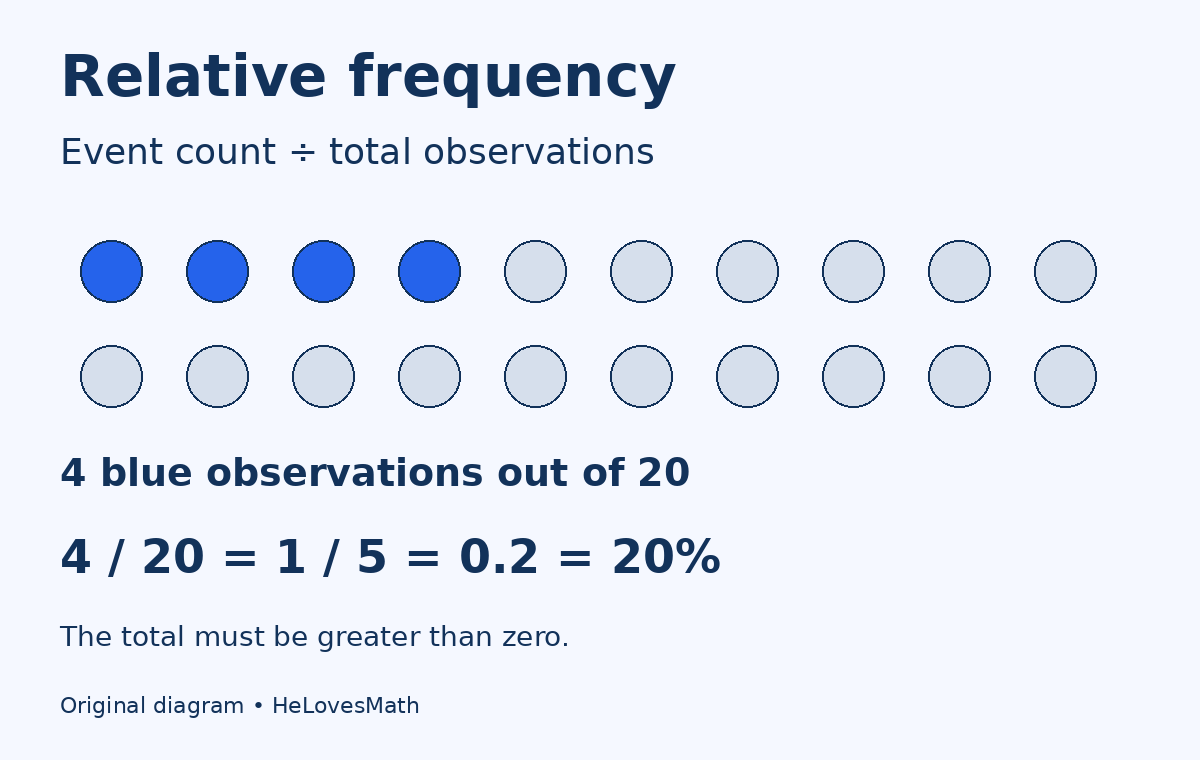
Within the rigorous scientific disciplines of statistics and advanced probability, Relative Frequency is defined strictly as a comparative ratio. It measures precisely how often a specific, unique event occurs divided by the overarching total volume of observational trials executed. Rather than merely stating "this happened 4 times," relative frequency powerfully declares "this happened 4 times absolutely out of 20 total global attempts, making it a 20% slice of reality."
To grasp why this metric represents such a profound paradigm shift beyond simple counting, you must recognize that standalone numbers lack context natively. If a basketball player proudly claims, "I successfully scored exactly 30 free throws," is that impressive? The raw number "30" alone offers zero qualitative insight.
- If he scored 30 throws out of 32 total attempts, he boasts an elite, magnificent level of skill (Rel. Freq = 93.75% (93.8% rounded to one decimal place)).
- If he scored 30 throws out of 200 total attempts, his performance was a monumental, historic disaster (Rel. Freq = 15%).
Relative Frequency physically generates the missing context. It converts useless, hovering raw tallies into highly aggressive, actionable proportional data that statisticians can easily utilize to model trends globally.
📐 The Universal Statistical Formulas
Deriving the relative frequency utilizes highly straightforward mathematical division logic. You identify the subgroup tally and surgically sever it by the absolute total tally matrix.
When analysts derive this outcome, the calculation inherently yields a number between 0 and 1 inclusive, provided the total n is greater than zero and 0 ≤ f ≤ n. However, translating this dense mathematical decimal into a universally legible percentage simply requires multiplication logic:
A Fundamental Rule: For mutually exclusive categories that cover every observation in a nonempty dataset exactly once, the exact relative frequencies total 1 (100%). Rounded displayed values may total slightly more or less than 100%. Overlapping events do not generally have this sum rule.
⚖️ Absolute vs. Relative vs. Cumulative Frequency
A staggering portion of academic grading errors stems from students fundamentally conflating the three primary tiers of statistical frequencies. Let us permanently delineate their categorical differences.
| Statistical Term | Definition | Practical Example Data |
|---|---|---|
| Absolute Frequency | The unedited, raw integer counting exactly how many times a single isolated event occurred. | "I saw absolutely 8 green cars drive by during the entire hour." |
| Relative Frequency | The absolute frequency cleanly divided by the sum of all trials, representing an analytical proportion. | "I observed 40 total cars. Therefore, 8 / 40 = 20% (0.2) were specifically green." |
| Cumulative Frequency | The running total of frequencies at or below a cutoff in an ordered variable or an explicitly stated category order. | "For journey durations of 5, 10 and 15 minutes with frequencies 5, 2 and 8, the cumulative frequency at 15 minutes is 5 + 2 + 8 = 15." Color counts of 5 red, 2 blue and 8 green cars also sum to 15 non-white cars, but colors have no natural cumulative order. |
Absolute provides the raw clay. Relative provides the comparative proportion. Cumulative adds frequencies in order up to a stated cutoff.
📝 How to Calculate It Step-by-Step (With Examples)
To mathematically calculate the exact ratio manually, perform these sequence-critical steps on your core overarching data set without deviance:
- Gather the Dataset and Establish the Sum Rule: First, you must account for every single observational trial executed within your experiment. You cannot leave data points missing. If you surveyed citizens about their favorite pets, count one response per person and use mutually exclusive categories covering all respondents.
- Isolate Your Target Subgroup Frequency (f): Mathematically define precisely what conditional event you are querying. Count how many total times this specific event happened. Example: You found that exactly 35 people surveyed preferred massive dogs.
- Establish the Total Count Magnitude (n): Add together the frequencies of absolutely every single category to find the overall universe size. If 35 preferred dogs, 15 preferred cats, and 10 preferred birds, your supreme total (n) equates to rigidly 60.
- Execute Division: Divide the specific target event (f) by the overarching global total (n). Calculation = 3560
- Synthesize the Decimals: The fractional equation 35/60 reduces accurately to a raw repeating decimal mathematically structured as 0.5833...
- Transpose to Percentage Formulation: Aggressively multiply the core decimal layout by 100 to shift the decimal boundary cleanly. This ultimately generates approximately 58.33% categorical relative frequency (rounded to two decimal places).
📊 Creating a Relative Frequency Distribution Table
When analysts process large, chaotic datasets featuring multiple categories simultaneously, they must rely heavily upon organizing the disparate metrics visually into a formal Relative Frequency Distribution Table. This universally standard spreadsheet matrix immediately clarifies data dispersion across a spectrum.
Consider a rigorous experimental trial rolling a simple physical six-sided die precisely 50 times in succession. Here is how the distribution table perfectly maps the chaotic outcome events:
| Dice Face Generated | Absolute Frequency (Count) | Relative Frequency (Fraction) | Relative Frequency (Decimal) |
|---|---|---|---|
| Rolled a 1 | 8 | 8 / 50 | 0.16 (16%) |
| Rolled a 2 | 12 | 12 / 50 | 0.24 (24%) |
| Rolled a 3 | 7 | 7 / 50 | 0.14 (14%) |
| Rolled a 4 | 9 | 9 / 50 | 0.18 (18%) |
| Rolled a 5 | 11 | 11 / 50 | 0.22 (22%) |
| Rolled a 6 | 3 | 3 / 50 | 0.06 (6%) |
| Column Summation Check | Total = 50 | 50 / 50 | Total = 1.00 (100%) |
Notice the critical summation check rigorously performed on the absolute bottom row. This mathematical law acts natively as an error-catching safety protocol. Check the original counts, denominator and category coverage if the sum is far from 1. Small differences may simply be rounding: three equal categories displayed as 33.33% each total 99.99%. Keep exact fractions or unrounded values for the check.
🌟 Why is it Critical in Probability Theory?
Relative frequency serves fundamentally as the sturdy conceptual bridge connecting purely experimental, chaotic reality directly to sterile, rigid mathematical theory. For a fair coin, the theoretical probability of heads on each toss is 0.5 (50%); this does not mean exactly half the tosses in every finite sample are heads. This is classified as entirely Theoretical Probability.
However, reality actively defies perfection. If you physically flip a fair coin exactly 10 times in reality, you will frequently witness highly skewed outcomes, such as 7 total Heads and 3 mere Tails. Your observed relative frequency for Heads fundamentally becomes precisely 0.70 (70%).
Relative frequencies can estimate unknown probabilities when observations are representative and conditions are sufficiently comparable. Larger samples reduce random variation under appropriate assumptions, but do not remove selection bias or changes in conditions. Historical outcomes, including medical outcomes, describe the sampled group and are not a guarantee or personalized prediction for a new case.
❌ Common Mathematical Mistakes to Avoid
When computing massive datasets under extreme pressure or tight exam deadlines, individuals frequently make completely avoidable, devastating mathematical infractions that utterly ruin categorical distributions.
- Excluding Null Datasets from the Total (n): If you are counting survey feedback logic and absolutely 10 individuals selected the specific "No Opinion" conditional response, you cannot simply throw those 10 datasets into the metaphorical garbage. They are incredibly vital events representing an active statistical choice. They must be aggressively fundamentally tallied into the overarching total number of trials (n). Omitting them mathematically inflates all remaining subset frequencies artificially.
- Mixing Up Variables During Algorithmic Division: A tragic error structurally involves accidentally plugging the grand total into the exact top fractional numerator location. If your absolute subset frequency is purely 10 explicitly out of 100 trials, the equation is 10 / 100 = 0.1. If you clumsily execute 100 / 10, you procure 10, incorrectly projecting a completely chaotic 1000% occurrence frequency! Remember logically: subset fundamentally always belongs distinctly on top.
- Excessive Premature Decimal Rounding: If you severely round fractional division decimals far too aggressively during the initial preliminary equations (rounding exactly 0.124 explicitly simply to 0.1), rounded totals may differ from 100%. Retain unrounded values for calculations, and label rounded results rather than treating a small rounding difference as a data error.
❓ Frequently Asked Questions (FAQ)
Sources
HeLovesMath.com — High-Performance Empirical Statistics Tools & Analytical Homework Calculators
© 2026 HeLovesMath. All interactive statistical algorithmic tools are securely structurally provided completely freely openly for explicit scholastic, educational, and stringent analytical research purposes directly.
Return to HeLovesMath Directory